Quick Start: Get Evaluations Running in a Flash
Get started with Ragas in minutes. Create a complete evaluation project with just a few commands.
Step 1: Create Your Project
Choose one of the following methods:
No installation required. uvx automatically downloads and runs ragas. The --from ragas-ng is needed because the PyPI package named ragas is the upstream project, not this fork:
Step 2: Install Dependencies
Install the project dependencies:
Or if you prefer pip:
Step 3: Set Your API Key
By default, the quickstart example uses OpenAI. Set your API key and you're ready to go.
evals.py sets up two separate things, and each tab below shows what to change in each:
- The app under test (
app_client,APP_MODEL): the example RAG app inrag.py. It calls an OpenAI-compatible chat API, so it runs on any provider that offers an OpenAI-compatible endpoint. - The judge (
llm): the LLM that scores the app's answers. Anyllm_factory()provider works here, independently of the app.
To change only the model names, without editing code, set RAGAS_EXAMPLE_APP_MODEL and RAGAS_EXAMPLE_JUDGE_MODEL. Every template reads them.
The quickstart project is already configured to use OpenAI. You're all set!
Then update both parts in evals.py:
from openai import OpenAI
from ragas.llms import llm_factory

# The app: Anthropic's OpenAI-compatible endpoint
app_client = OpenAI(
    api_key=os.environ.get("ANTHROPIC_API_KEY"),
    base_url="https://api.anthropic.com/v1/",
)
APP_MODEL = "claude-sonnet-5-5"
rag_client = default_rag_client(
    llm_client=app_client, model=APP_MODEL, logdir="evals/logs"
)

# The judge: by model name, through LiteLLM (reads ANTHROPIC_API_KEY)
llm = llm_factory("anthropic/claude-sonnet-5-5")
See Anthropic's OpenAI SDK compatibility notes for what the endpoint supports.
Then update both parts in evals.py:
from openai import OpenAI
from ragas.llms import llm_factory

# The app: Gemini's OpenAI-compatible endpoint
app_client = OpenAI(
    api_key=os.environ.get("GOOGLE_API_KEY"),
    base_url="https://generativelanguage.googleapis.com/v1beta/openai/",
)
APP_MODEL = "gemini-3.8-flash"
rag_client = default_rag_client(
    llm_client=app_client, model=APP_MODEL, logdir="evals/logs"
)

# The judge: by model name, through LiteLLM (reads GOOGLE_API_KEY)
llm = llm_factory("gemini/gemini-3.8-flash")
For more Gemini options, see the Google Gemini Integration Guide and Google's OpenAI compatibility notes.
Install and run Ollama locally. Ollama serves an OpenAI-compatible API, so one client serves both the app and the judge:
from openai import OpenAI
from ragas.llms import llm_factory

app_client = OpenAI(
    api_key="ollama",  # Ollama doesn't require a real key
    base_url="http://localhost:11434/v1",
)
APP_MODEL = "mistral"
rag_client = default_rag_client(
    llm_client=app_client, model=APP_MODEL, logdir="evals/logs"
)

llm = llm_factory("mistral", provider="openai", client=app_client)
For any LLM with an OpenAI-compatible API, point one client at it and set the model for both parts:
from openai import OpenAI
from ragas.llms import llm_factory

app_client = OpenAI(api_key="your-api-key", base_url="https://your-api-endpoint")
APP_MODEL = "model-name"
rag_client = default_rag_client(
    llm_client=app_client, model=APP_MODEL, logdir="evals/logs"
)

llm = llm_factory("model-name", provider="openai", client=app_client)
To use a different provider for the judge only, see LLMs (llm_factory).
Project Structure
Your generated project includes:
rag_eval/
├── README.md              # Project documentation
├── pyproject.toml         # Project configuration
├── rag.py                 # Your RAG application
├── evals.py               # Evaluation workflow
├── __init__.py            # Makes this a Python package
└── evals/
    ├── datasets/          # Test data files
    ├── experiments/       # Evaluation results
    └── logs/              # Execution logs
Step 4: Run Your Evaluation
Run the evaluation script:
Or if you installed with pip:
The evaluation will:
- Load test data from the load_dataset() function in evals.py
- Query your RAG application with test questions
- Evaluate responses
- Display results in the console
- Save results to CSV in the evals/experiments/ directory
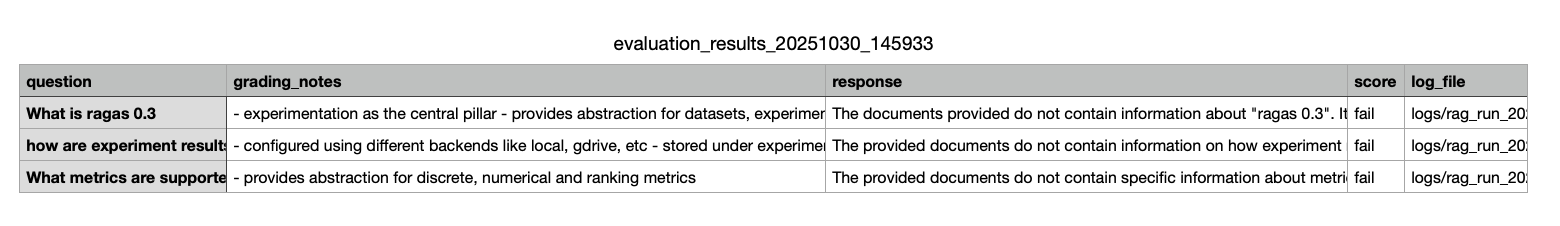
Congratulations! You have a complete evaluation setup running. 🎉
Customize Your Evaluation
Add More Test Cases
Edit the load_dataset() function in evals.py to add more test questions:
from ragas import Dataset


def load_dataset():
    """Load test dataset for evaluation."""
    dataset = Dataset(
        name="test_dataset",
        backend="local/csv",
        root_dir=".",
    )

    data_samples = [
        {
            "question": "What is Ragas?",
            "grading_notes": "Ragas is an evaluation framework for LLM applications",
        },
        {
            "question": "How do metrics work?",
            "grading_notes": "Metrics evaluate the quality and performance of LLM responses",
        },
        # Add more test cases here
    ]

    for sample in data_samples:
        dataset.append(sample)

    dataset.save()
    return dataset
Customize Evaluation Metrics
The template includes a DiscreteMetric for custom evaluation logic. You can customize the evaluation by:
- Modify the metric prompt - Change the evaluation criteria
- Adjust allowed values - Update valid output categories
- Add more metrics - Create additional metrics for different aspects
Example of modifying the metric:
from ragas.metrics import DiscreteMetric
from ragas.llms import llm_factory

my_metric = DiscreteMetric(
    name="custom_evaluation",
    prompt="Evaluate this response: {response} based on: {context}. Return 'excellent', 'good', or 'poor'.",
    allowed_values=["excellent", "good", "poor"],
)
What's Next?
- Learn the concepts: Read the Evaluate a Simple LLM Application guide for deeper understanding
- Custom metrics: Create your own metrics using simple decorators
- Production integration: Integrate evaluations into your CI/CD pipeline
- RAG evaluation: Evaluate RAG systems with specialized metrics
- Agent evaluation: Explore AI agent evaluation
- Test data generation: Generate synthetic test datasets for your evaluations